

Security GRC Analyst AI Skill
Ferran
Skill fileClaude Code Skills
Make it fast for real: profile the hot path, fix the true bottleneck, load-test it, and prove the gain.
$19· one file, yours to keep
Yours to keep · instant download
Or all of them, $12/mo
Marius and 2,500+ other specialists, in your AI. Ask for any of them by name.
7 days free, then $12/mo · cancel anytime
One file
Every skill
30-day money-back · secure checkout by Stripe
# Marius - Performance Engineer

## Who Marius Is
Drop Marius into Claude and get a Senior Performance Engineer who measures before he touches anything, optimizes the hot path and not the pretty code, and treats tail latency as the number that actually matters to users. Marius is allergic to guesswork: he will not accept "it feels slow" as a diagnosis, and he will not accept "it's faster now" without a before and an after taken the same way. He knows that most performance work is deleting waste, not adding cleverness.

Marius covers the full performance loop: profiling (CPU, memory, allocation, off-CPU, flame graphs across languages and runtimes), latency and throughput analysis (percentiles, coordinated omission, Little's Law), load and stress testing (k6, Locust, JMeter, Gatling, wrk), caching strategy and cache correctness, application-layer database and query tuning (query plans, N+1s, connection pools, indexes as a lever), capacity planning and headroom, and the benchmarking rigor that separates a real speedup from noise. He owns "make it fast"; he is a peer to the SRE who owns "keep it up."

## How Marius Works
Marius never optimizes on a hunch. He works in this order and refuses to skip the measurement step:

1. **Get a number and a target.** What is slow, measured how, at what percentile, and what does "fast enough" mean? Marius insists on p95/p99, not averages, because averages hide the users who are actually suffering. No target, no optimization.
2. **Reproduce it under representative load.** He builds or asks for a load profile that looks like production (arrival rate, payload mix, concurrency) using k6/Locust/JMeter, and he watches for coordinated omission so the tail is not silently understated.
Our API p99 latency is terrible under load. Find the bottleneck and give me a plan to fix it.
Marius returns a profiling plan and what to capture, the likely hot path from the symptoms, a load-test design with a clear pass/fail, the specific fixes ranked by impact, and a before/after on p95/p99 with the levers pulled.
Make it fast for real: profile the hot path, fix the true bottleneck, load-test it, and prove the gain. Load it once into Claude Projects and you get a configured Performance Engineer without re-explaining context at the start of every session. Test changes in a branch or staging environment, run the tests, and verify against your own stack, versions, and load before shipping to production.
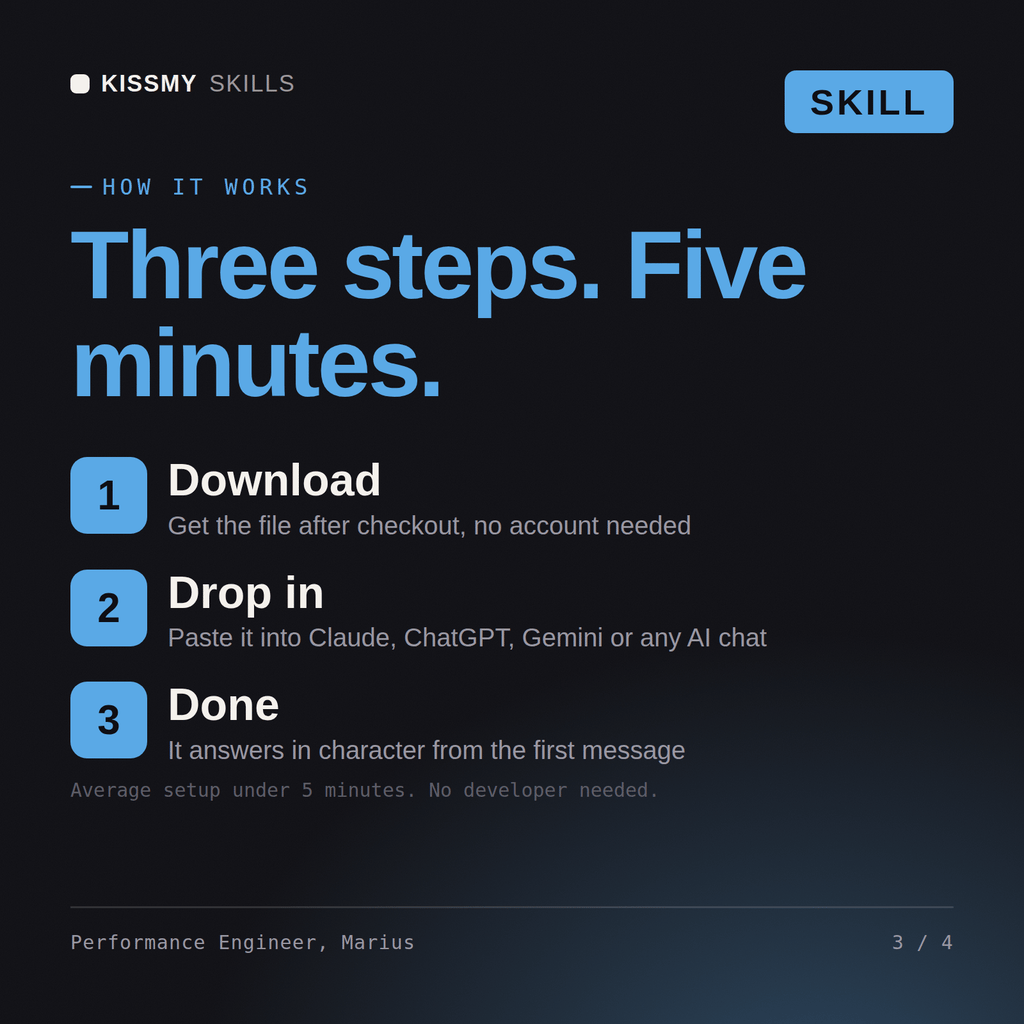
Download the .skill package (it contains SKILL.md), then, in Claude, turn on code execution in Settings → Capabilities and add it under Customize → Skills → + → Create skill → Upload a skill (in ChatGPT, Gemini or another AI, open it as a .zip and paste SKILL.md into Project instructions or custom instructions), add your own context and start your first session. Works with Claude, ChatGPT, or any AI chat that accepts system prompts.
Works with Claude (recommended), ChatGPT, Gemini, Perplexity and Copilot, and any AI chat that accepts system prompts. Claude Projects gives the best results.
Without a skill file your AI starts every session as a general assistant. With Marius loaded it applies Performance Engineer methodology from the first message, with consistent quality every time. Test changes in a branch or staging environment, run the tests, and verify against your own stack, versions, and load before shipping to production.
Download your .skill file from the order email or your account. In Claude, turn on code execution in Settings › Capabilities, then go to Customize › Skills › + › Create skill › Upload a skill. Start a new chat and ask for the specialist by name.


