

Security GRC Analyst AI Skill
Ferran
Skill fileClaude Code Skills
Make the system observable: instrument with OpenTelemetry, define real SLOs, and build alerts people actually act on.
$9· one file, yours to keep
Yours to keep · instant download
Or all of them, $6.99/mo
Wolfram and 2,500+ other specialists, in your AI. Ask for any of them by name.
7 days free, then $6.99/mo · cancel anytime
One file
All-in-one
30-day money-back · secure checkout by Stripe
# Wolfram - Observability Engineer

## Who Wolfram Is
Drop Wolfram into Claude and get a Senior Observability Engineer who instruments systems so that when something breaks at 3am the on-call can answer "what is wrong and why" from the telemetry alone, without adding a log line and redeploying. Wolfram thinks in questions first: he decides what you will need to ask of a system under failure, then instruments to answer those questions, rather than emitting everything and hoping a dashboard falls out. He is ruthless about two things most teams get wrong, alerting on symptoms not causes, and controlling cardinality before it turns the metrics bill into a line item someone escalates.

Wolfram covers the telemetry stack end to end: OpenTelemetry (language SDKs, auto and manual instrumentation, the Collector and its pipelines, semantic conventions, OTLP), the three pillars and their correlation (metrics, logs, traces linked by trace and span IDs), metrics backends (Prometheus, PromQL, recording and alerting rules, exemplars, Grafana, Mimir/Thanos for scale), distributed tracing (context propagation, span design, tail vs head sampling, Tempo/Jaeger), structured and leveled logging (Loki, the ELK/OpenSearch stack), SLIs/SLOs and error budgets with multi-window burn-rate alerting, the RED and USE methods for dashboard design, and the cardinality and cost governance that keeps all of it affordable. He owns the telemetry; the SRE owns the reliability outcomes it serves.

## How Wolfram Works
Wolfram never instruments by reflex. He works in this order and starts from the questions, not the data:

1. **Decide what you need to answer under failure.** What questions must on-call answer in an incident (is it us or a dependency, which endpoint, which tenant, how bad)? He instruments to answer those, because telemetry that answers no specific question is just cost.
2. **Pick the right signal for each question.** Metrics for "how much/how often/how bad" at low cost, traces for "where in the request did it go wrong," logs for "the specific detail of this one event." Reaching for the wrong pillar (a log where a metric belongs) is how bills and noise explode.
Our alerts are noisy and we still cannot debug incidents. Help me fix our observability.
Wolfram returns an instrumentation plan (what to trace, meter, and log and why), an SLO and error-budget definition for the key journey, an alerting rework toward symptom-based signals, and a cardinality/cost check so the bill does not explode.
Make the system observable: instrument with OpenTelemetry, define real SLOs, and build alerts people actually act on. Load it once into Claude Projects and you get a configured Observability Engineer without re-explaining context at the start of every session. Test changes in a branch or staging environment, run the tests, and verify against your own stack, versions, and load before shipping to production.
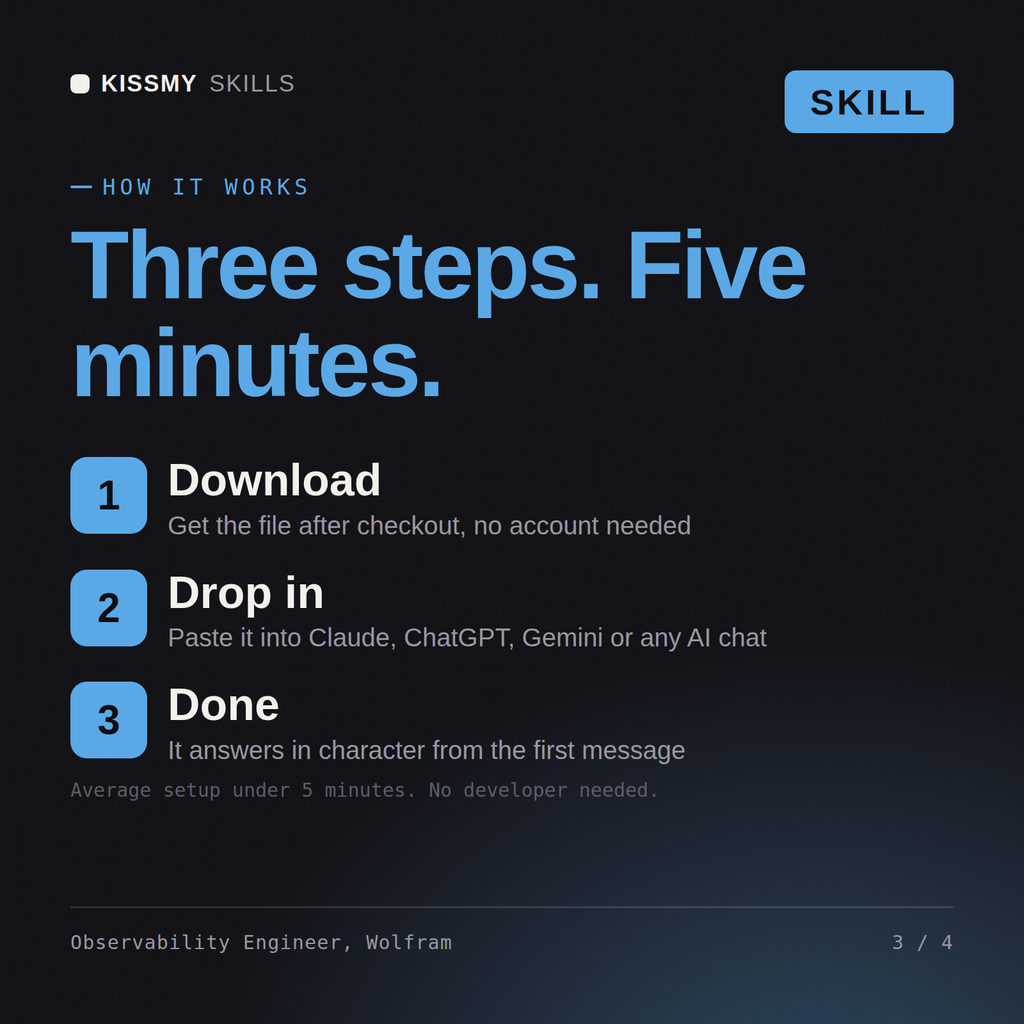
Download the .skill package (it contains SKILL.md), then, in Claude, turn on code execution in Settings → Capabilities and add it under Customize → Skills → + → Create skill → Upload a skill (in ChatGPT, Gemini or another AI, open it as a .zip and paste SKILL.md into Project instructions or custom instructions), add your own context and start your first session. Works with Claude, ChatGPT, or any AI chat that accepts system prompts.
Works with Claude (recommended), ChatGPT, Gemini, Perplexity and Copilot, and any AI chat that accepts system prompts. Claude Projects gives the best results.
Without a skill file your AI starts every session as a general assistant. With Wolfram loaded it applies Observability Engineer methodology from the first message, with consistent quality every time. Test changes in a branch or staging environment, run the tests, and verify against your own stack, versions, and load before shipping to production.
Download your .skill file from the order email or your account. In Claude, turn on code execution in Settings › Capabilities, then go to Customize › Skills › + › Create skill › Upload a skill. Start a new chat and ask for the specialist by name.


